

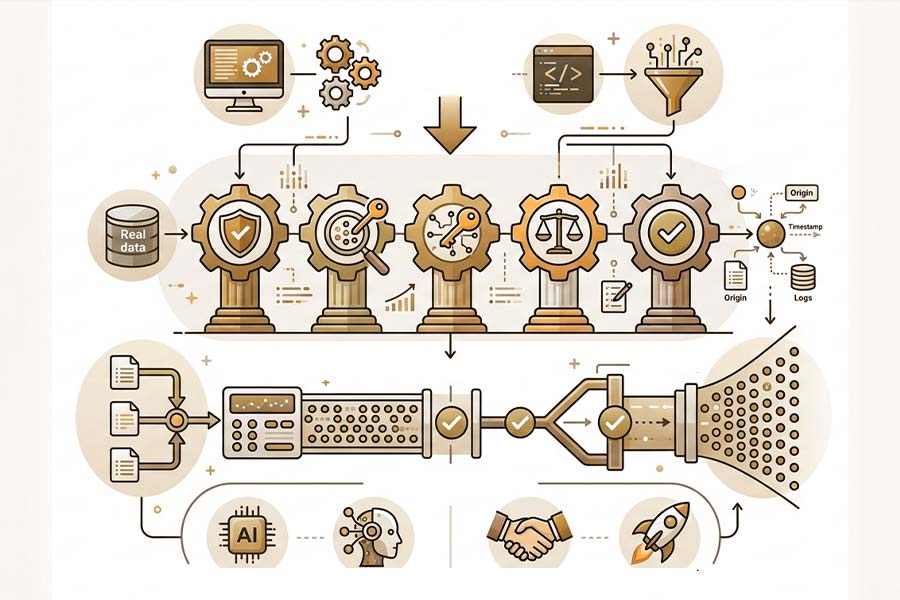
Synthetic data can provide AI teams with more examples for model training, testing, and handling rare cases when real records are restricted. It can also carry source bias, expose sensitive patterns, distort rare cases, or lose value when reused for another task.
Synthetic data governance gives leaders a way to control those risks from creation through retirement. The goal is to know what generated each dataset, what it represents, where teams can use it, and what evidence supports that use. As synthetic data moves across more models, traceability becomes the link between speed and trust.
What should synthetic data solve before teams generate it?
Teams should start with the business problem. The generator comes after the use case is clear. Synthetic data can support testing, data sharing, rare-event coverage, or model training.
Test data may need realistic workflow patterns. Training data needs proof that it improves model performance. Data prepared for external sharing needs a stronger privacy assessment.
A vague purpose can lead teams to generate large datasets that look convincing and add little value. Defining the use case gives validation teams a clear target.
Why should Synthetic Data Governance start with data lineage?
Traceability begins with the real data used to create synthetic records. Teams need to know which source population, time, and fields shaped the generated dataset.
That record should continue through generation. Capture the generator, model version, parameter settings, and approval owner. Then connect the dataset with every training run or test that uses it.
This creates a chain of evidence. When model performance drops, teams can trace the issue to the source data, the generation method, the validation step, or the reuse decision. That evidence should then travel with the dataset.
Also Read: CIO Influence Interview with John Elliott, Cybersecurity Author Fellow at Pluralsight
What evidence should follow each synthetic dataset?
A useful dataset record provides AI teams with enough context to determine whether the asset still fits its approved task.
| Evidence area | What teams should record |
| Source | Dataset, collection period, population scope and approved use |
| Generation | Method, model version, settings and generation date |
| Validation | Privacy tests, bias checks, task results and known limits |
| Ownership | Data owner, approval owner, review date and reuse status |
Synthetic data governance works better when this record travels with the dataset. Teams can review the evidence before moving data into another model, pipeline or business use.
How should teams test privacy leakage and bias?
Synthetic records can sit too close to source records or carry patterns that disadvantage some groups. Teams need privacy and fairness tests before release.
-
Similarity risk:
Look for generated records that closely resemble source records, with extra attention to rare combinations of attributes.
-
Membership risk:
Test whether an attacker could infer that a person appeared in the source dataset.
-
Attribute risk:
Check whether known details could reveal sensitive information about a source record.
-
Representation checks:
Compare subgroup distributions and downstream error patterns across real and synthetic data.
NIST warns that synthetic data without differential privacy may remain open to privacy attacks. This makes measured privacy evidence part of dataset approval.
How can teams prove synthetic data is useful for real tasks?
Strong statistical similarity can still hide weak task performance. A dataset may preserve broad distributions while losing relationships that drive the model outcome.
Teams should compare synthetic data with a trusted real-data holdout. One useful test is to train on synthetic data and evaluate on real data. Review accuracy, error types, rare-event performance, and stability.
Synthetic data governance should also capture tradeoffs. Extra-rare-event examples may improve detection while raising false alarms elsewhere. Recording both effects gives decision makers a clearer view of where the dataset adds value and where extra review is required.
How should teams label synthetic data across AI pipelines?
Once generated data enters shared pipelines, labels keep its origin visible and reduce unplanned reuse.
- Tag records or datasets as synthetic at ingestion.
- Attach source lineage, generation method, and approved purpose.
- Keep validation results with the dataset version used in training.
- Record each model or experiment that consumes the dataset.
- Flag reuse outside the approved task for a fresh review.
These labels give data, risk, engineering, and compliance teams the same context. They also support faster model investigations.
What retention and reuse rules should teams set?
Synthetic data can become stale when customer behavior, products, or source populations change. Retention should follow purpose and evidence.
Set a review date when the dataset receives approval. A new model, a new use case, a major source change, or a new market should trigger another validation cycle. Retire old versions through controlled deletion or archive rules so copied datasets stay out of future training.
Synthetic data governance should preserve generation records, validation evidence, and reuse history while the dataset is active. Future teams can then judge the asset before reuse.
Why does synthetic data need proof before trust?
Synthetic data can help teams expand training coverage while reducing direct use of real records. Its value comes from evidence showing how it was created and where it remains fit for use.
Synthetic data governance gives AI leaders that evidence. It integrates lineage, privacy testing, task validation, and reuse controls into a single operating process.
The principle is simple: synthetic data should earn trust through traceability and testing before it scales to training data.
Catch more CIO Insights: How Are CIOs Aligning Technology with Workforce Agility?
[To share your insights with us, please write to psen@itechseries.com ]
